GroovyMorning_RLAC
Data Creation for Training AI Models
Artificial intelligence relies heavily on data quality. To enable the system to detect a radio chronicle with precision, learning the acoustic and textual characteristics of chronicles was necessary, leading to the construction of a “Ground Truth” (ground truth) from scratch.
The Concept of “Ground Truth”
In AI, Ground Truth refers to the reference dataset for which the exact answer is known. In this context, it corresponds to thousands of radio segments accompanied by precise labels, for example: “Start of the Geopolitics Column at 08:16:04”.
The Automated Creation Pipeline
Since manual data collection was unfeasible, an automated process was implemented by leveraging official archives:
- Scraping (Radio France API): Official podcasts, already segmented into chronicles by Radio France, are retrieved to serve as reference models.
- Temporal Alignment: The full broadcast is downloaded in parallel.
- Audio Cross-Correlation: Through mathematical signal analysis, podcast chronicles are located within the live stream to obtain the exact timecode under live conditions (including surrounding ads and jingles).
From Audio to Text: Dataset Generation
After isolating segments, different types of data are generated for model training:
- Audio Data: Extraction of features (MFCC, Spectrograms) for jingle detection.
- Textual Data: Use of Whisper and Kyutai to obtain synchronized transcriptions (.srt files).
- Semantic Labeling: Identification of transition phrases (“It is 8:15”, “See you tomorrow Pierre”) with Kyutai for NLP model training (CamemBERT) by transcribing the first 10 seconds of each broadcast and then extracting the first sentence of that transcription.
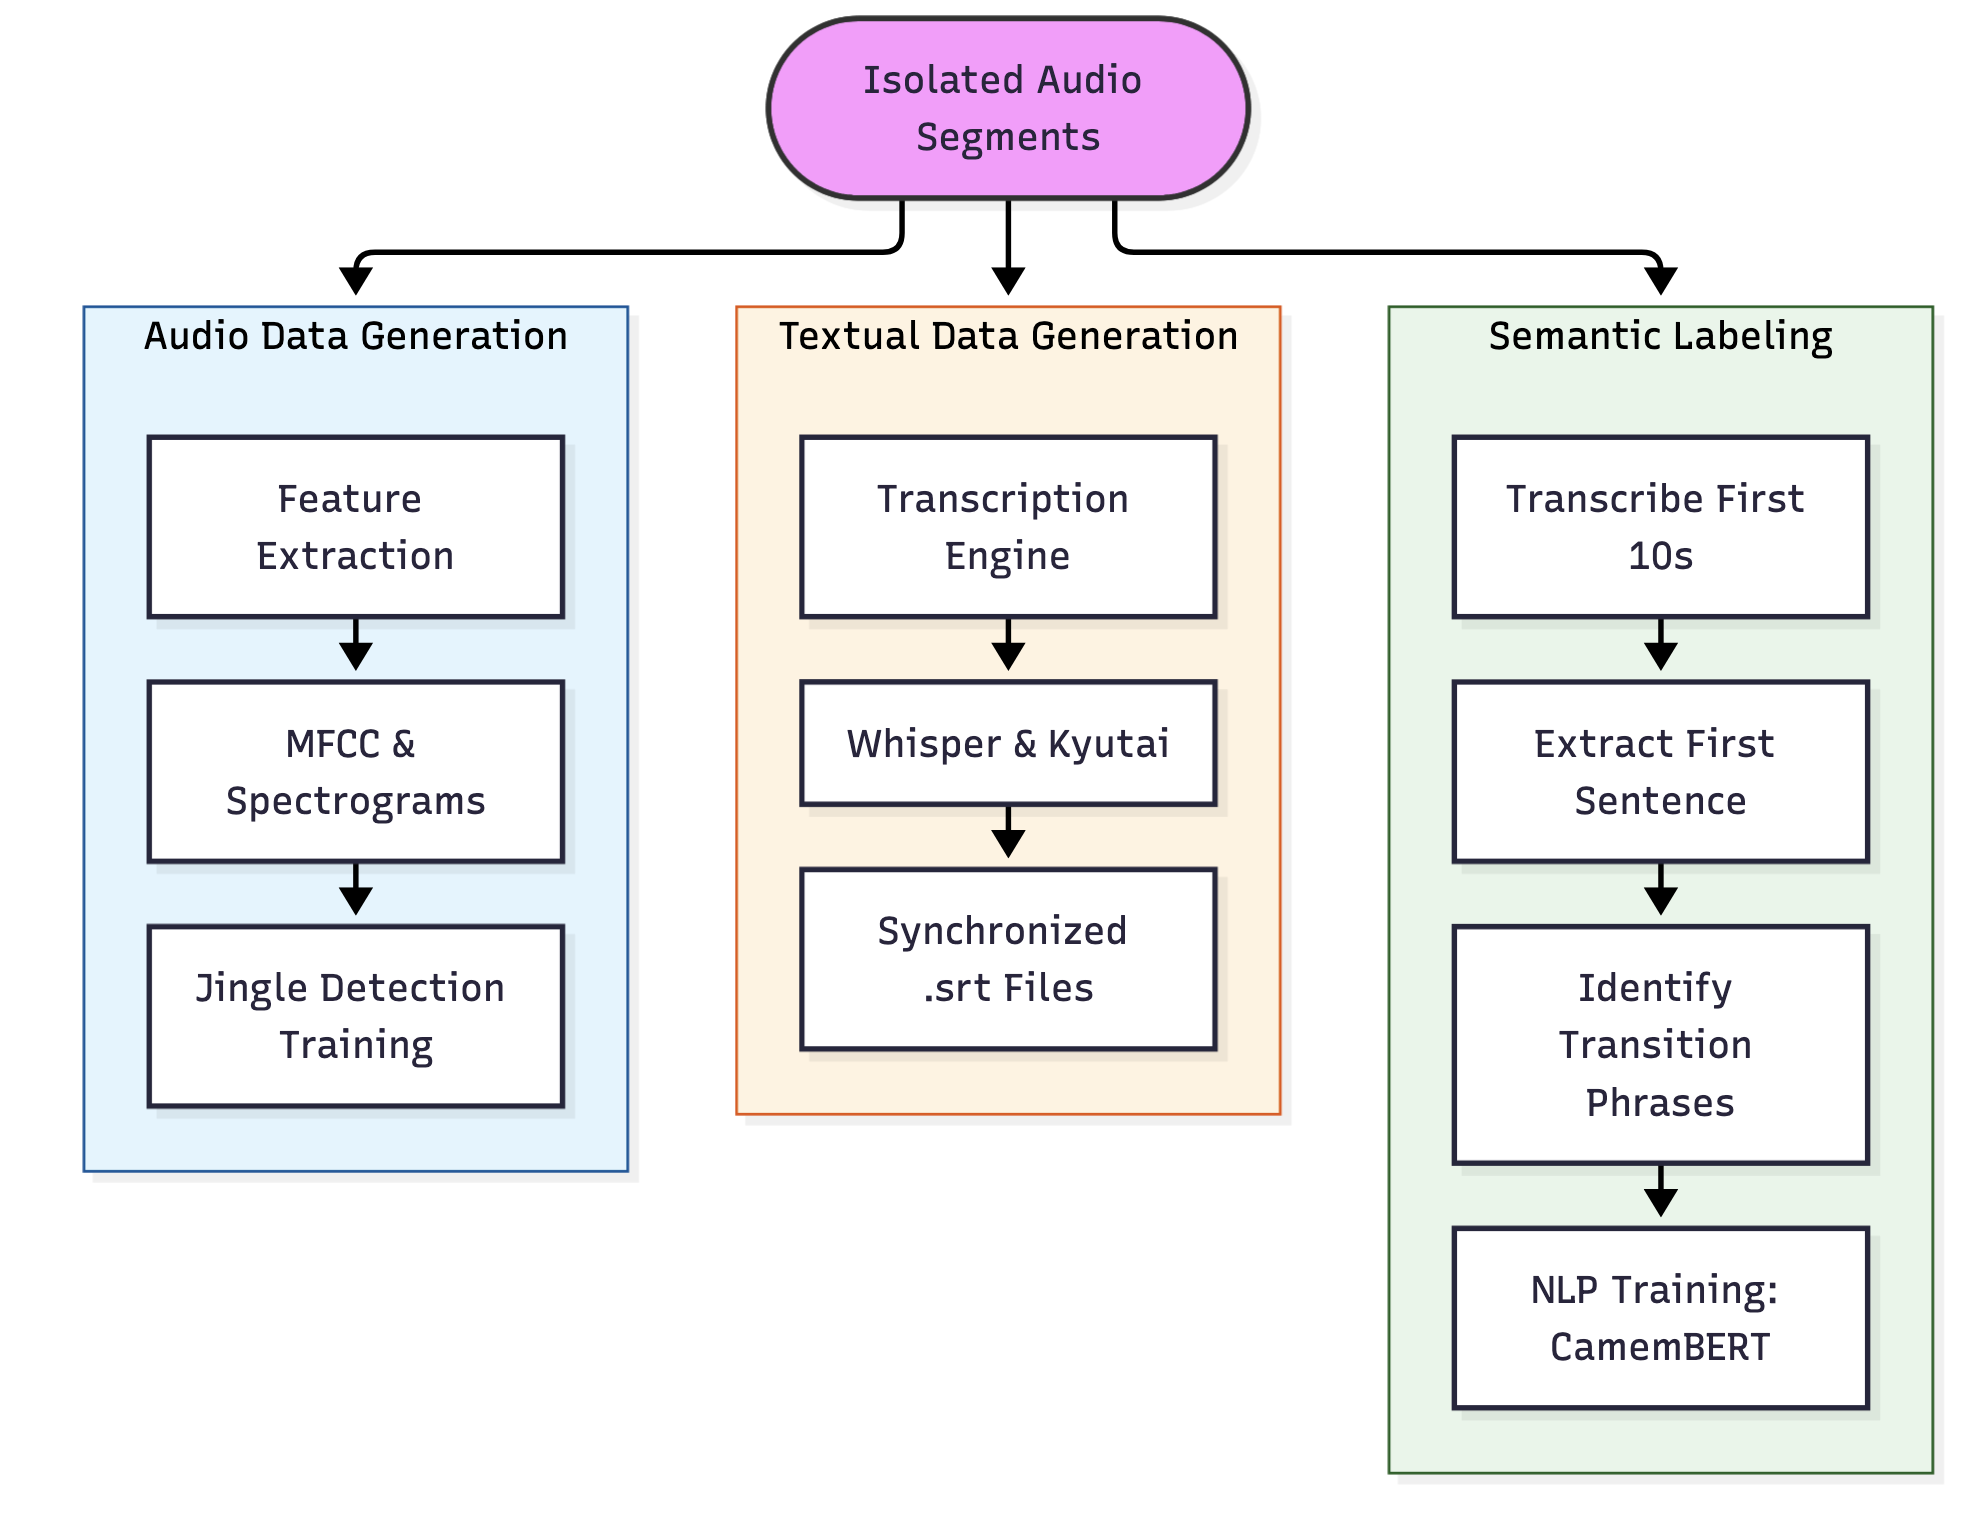
Generation is detailed in this article for audio and this article for text.
Human-in-the-loop: The Verification Interface
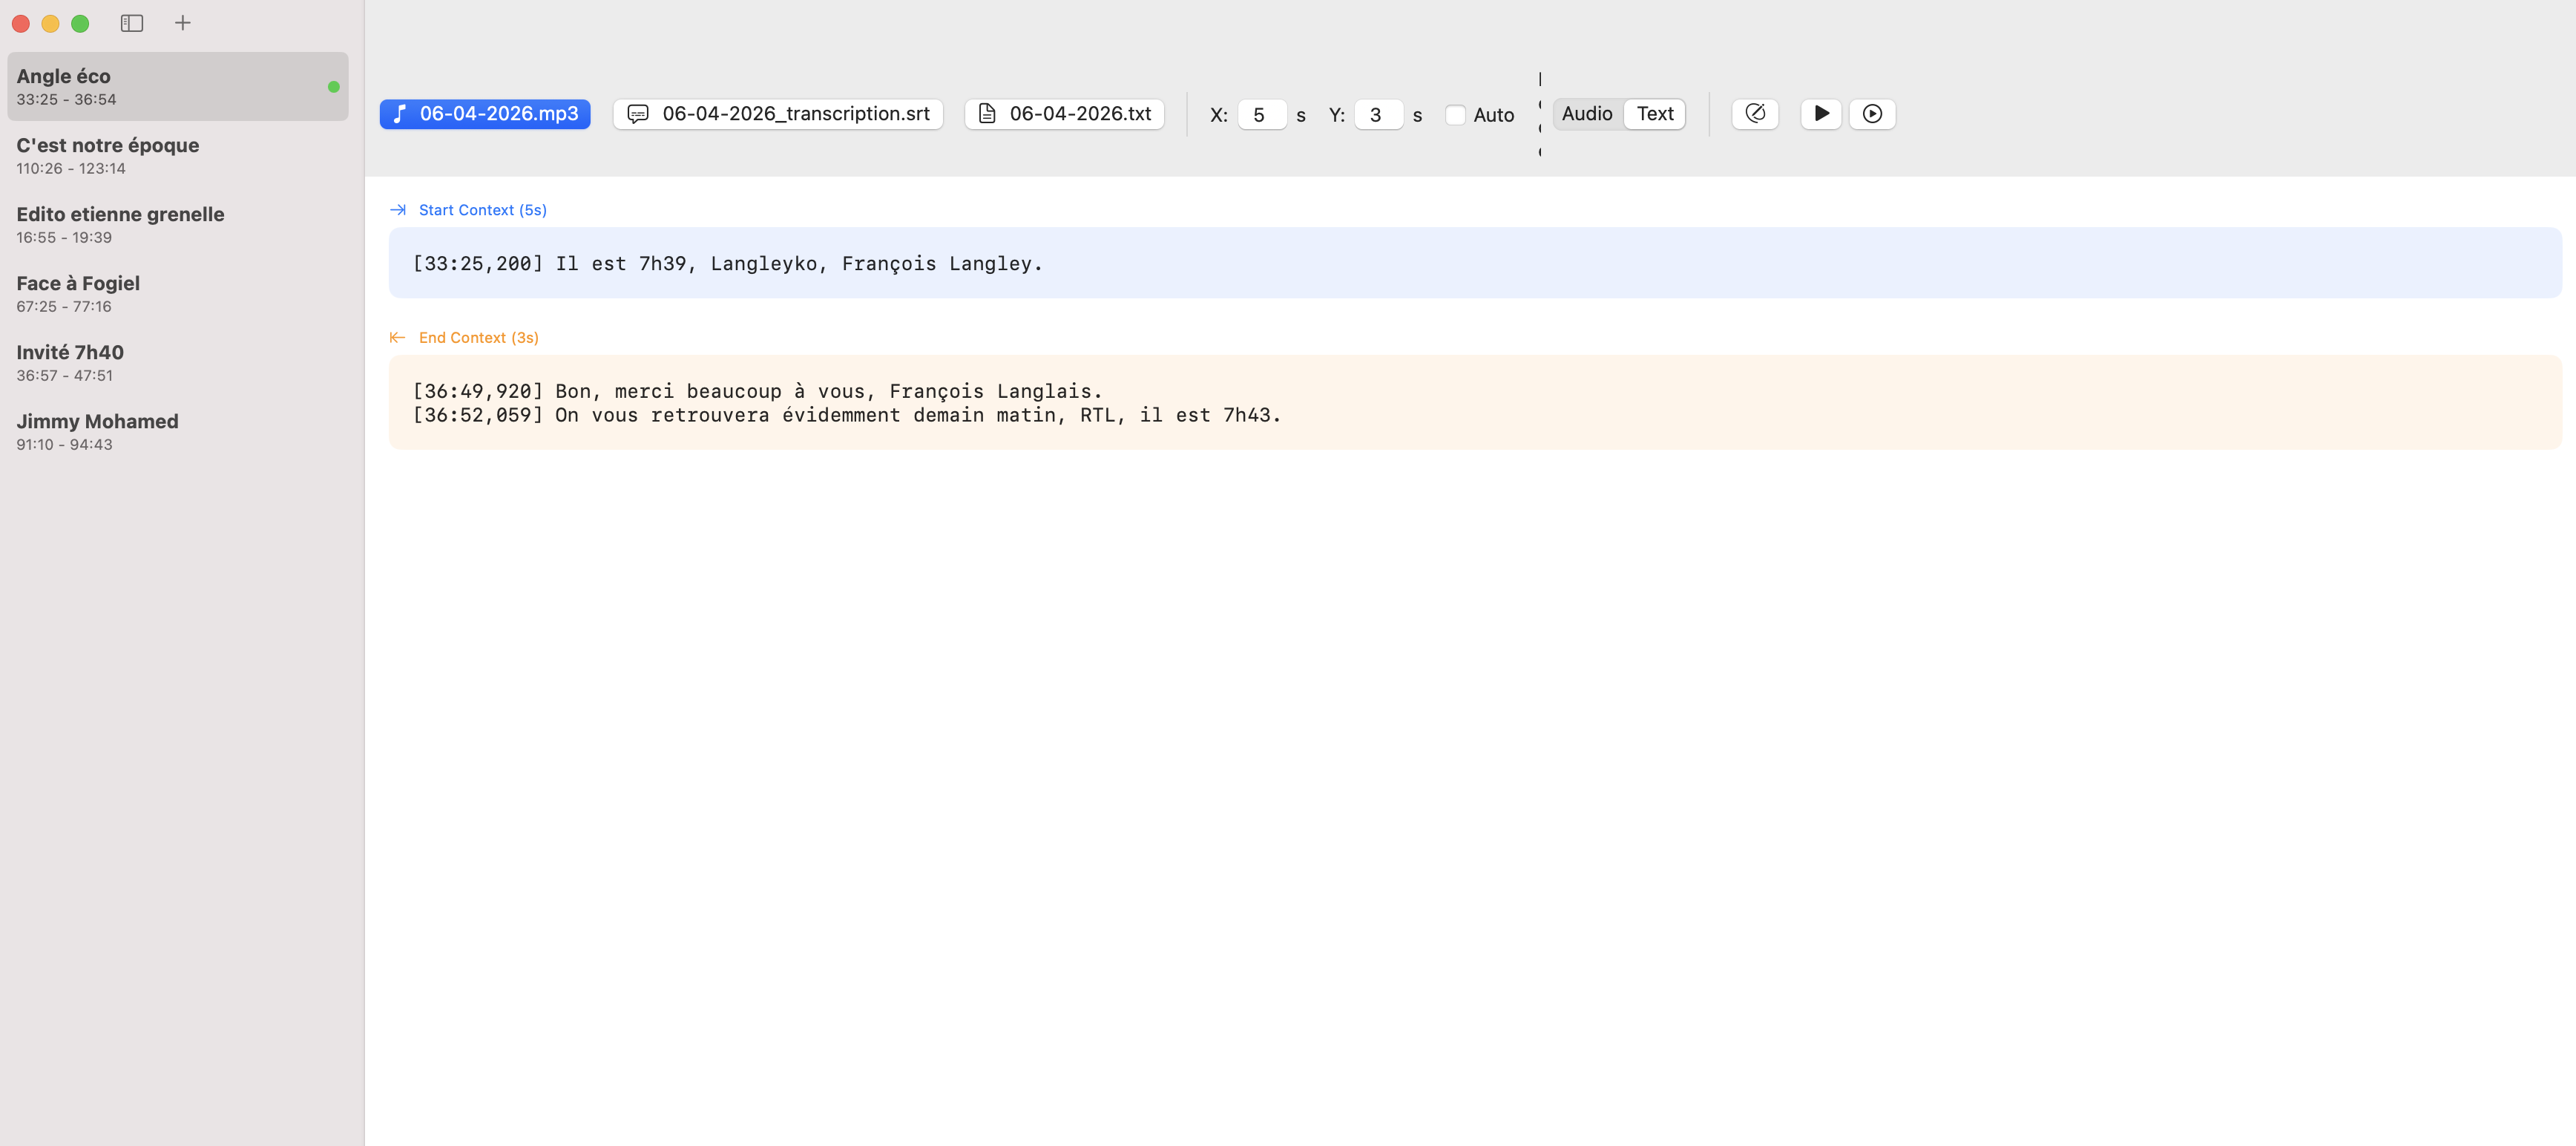
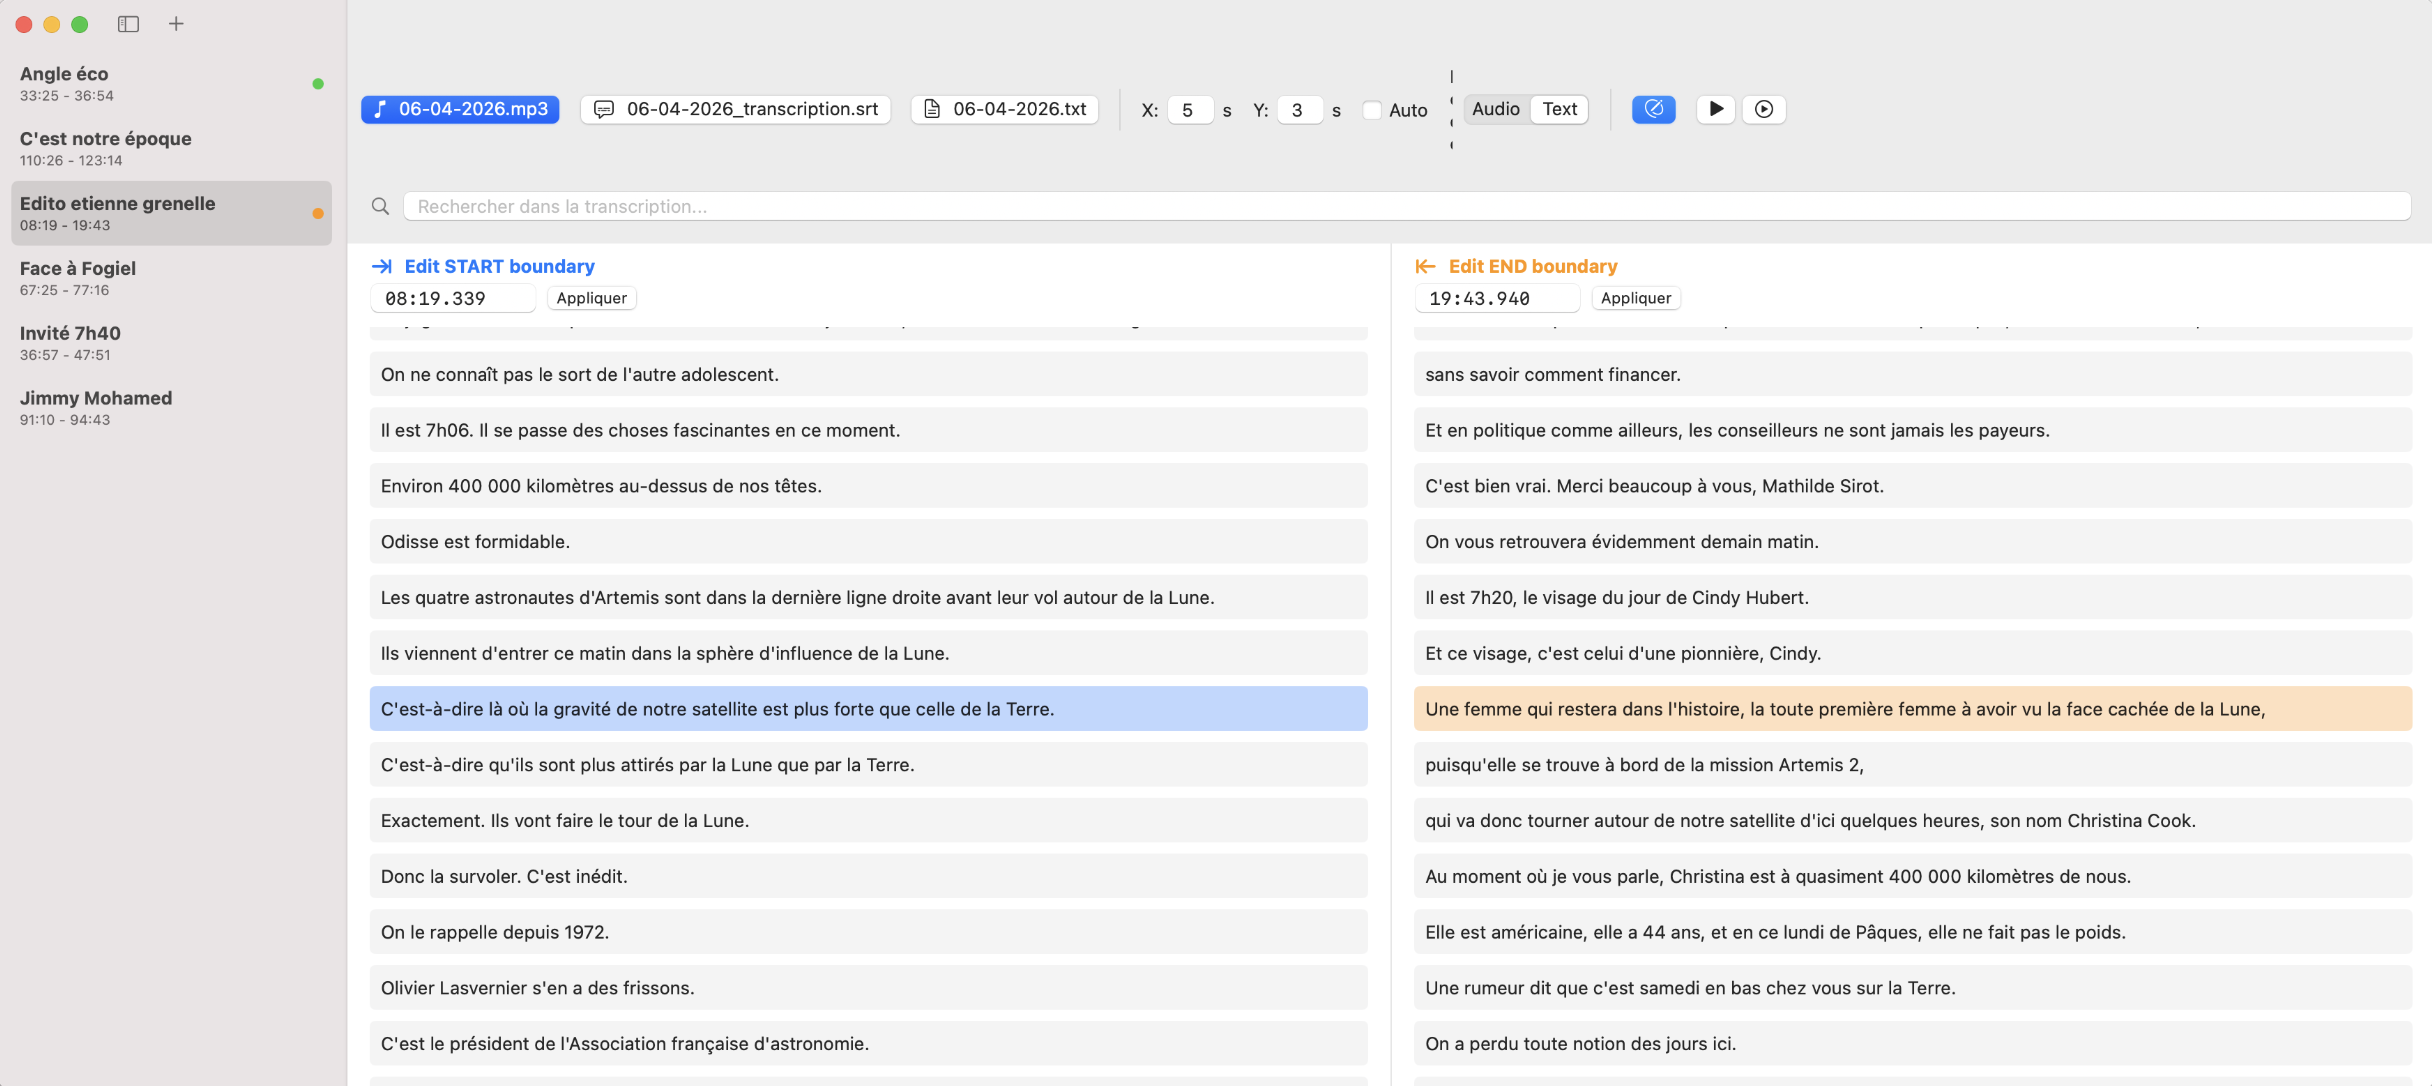
In a previous method, entire radio broadcasts were transcribed and then an LLM tried to locate the different chronicles within the broadcast. To allow faster manual verification of LLM detections, a dedicated interface, SegmentTimecodeVerification, was developed to ensure optimal quality of the test dataset.
This tool allows human intervention to:
- Listen to the segment detected by the AI.
- Visualize the transcription in parallel.
- Adjust the start/end slider to the millisecond.
- Validate or reject the detection.
Visualization of the chronicle start and end phrases
Manual editing of the start and end phrases
Diversity Challenges
Dataset variety was a priority, including:
- Different voices (gender and accent diversity).
- Different times of day (fast-paced morning shows vs. calm late-night shows).
- Complex cases (chronicles starting with music, telephone interviews).
Version française : Création de Données pour entraîner les modèles d’IA